
AI spend for delivery teams
Know where AI spend goes before it surprises your project budget.
Trace consumption to the sessions and models behind it. Investigate expensive runs and compare alternatives using both cost and task outcomes.
ClawMetry records what each agent session consumed, by runtime, model and session, on the machine the agent runs on. Every amount on this page says how it was calculated and what it leaves out. An estimate is never shown as a bill.
One amount, calculated in the open
This is the Top Sessions by Cost table from the released open-source dashboard. Two sessions were seeded for the screenshot; neither is customer data.
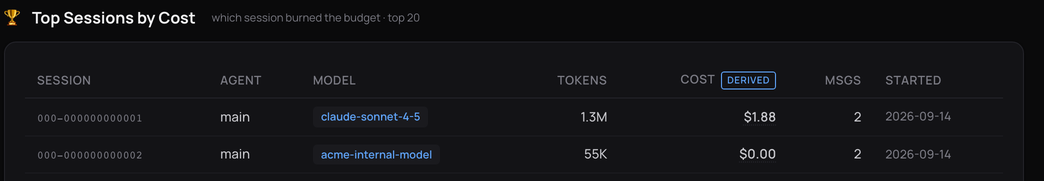
Here is how $1.88 is reached. Each token category is priced separately, because a cached read costs a tenth of a fresh input token and a naive total overstates the amount.
| Token category | Tokens | Published rate, USD per 1M | Amount, USD |
|---|---|---|---|
| Input | 200,000 | $3.00 | $0.600 |
| Output | 40,000 | $15.00 | $0.600 |
| Cache read (0.1 × input rate) | 1,000,000 | $0.30 | $0.300 |
| Cache write (1.25 × input rate) | 100,000 | $3.75 | $0.375 |
| Total | 1,340,000 | $1.875, shown as $1.88 |
- Source: the runtime's own cost figure for the call, as recorded in the session file. For this test session it was set to the published rates above, so you can check it by hand. Where a runtime records tokens but no cost figure, clawmetry 0.12.876 does not always price them: OpenClaw usage written with its
input,output,cacheReadandcacheWritekeys and no cost figure is stored as $0.00, and self-hosted models are stored as $0.00. Read those rows as unpriced, as described under the gaps below. - Period: one session on September 14, 2026. Timezone: UTC. Currency: USD.
- Rates: the pricing table in clawmetry 0.12.876 (claude-sonnet-4-5 at $3.00 input and $15.00 output per million tokens; Anthropic cache reads at 0.1 and cache writes at 1.25 times the input rate).
- Basis: usage value at published rates. It is not what your organisation was invoiced.
The full method is in How cost is computed.
Three kinds of money, kept apart
A cost figure is only useful if you know which of these it is. ClawMetry produces the first one today.
| View | What it is | Where it comes from | Status |
|---|---|---|---|
| Usage value at published rates | Recorded tokens priced at the provider's published per-token rates, or the runtime's own cost figure | Session files and the pricing table on the machine | Available |
| Expected contract spend | The same usage valued at your negotiated rates, with the rate version it was priced from | Your rate card, supplied by you | Pilot objective, not available today |
| Allocated actual spend | Amounts from an invoice or billing export, allocated to teams and projects | Your billing records. ClawMetry does not read invoices today. | Pilot objective, not available today |
Two readings to avoid. A cost that a runtime or an LLM gateway reports may itself be an estimate at published rates, not a charge. And if your team uses a subscription plan, the API-equivalent value of that usage shows how much was consumed. It is not an additional bill, and the plan fee is not included in it.
What is not priced, and what is not assigned
A total that silently leaves things out is worse than no total. Look for these two gaps before you quote a number.
- Unpriced usage. The second row in the screenshot is a model with no published rate and no runtime-recorded cost. Its 55K tokens are recorded, but in clawmetry 0.12.876 it shows
$0.00. Read $0.00 next to a non-zero token count as unpriced usage, not free usage, and leave it out of any cost claim until it is priced. - Unassigned usage. In clawmetry 0.12.876 you map a runtime to a team, and the team rollup follows those runtime mappings. A runtime you have not mapped appears under its own runtime name, not under a team and not under an unassigned total, so check the rollup for raw runtime names before you quote a team figure. An explicit unassigned residual, like the one in the sample report below, is a pilot objective, not available today. Mapping is described in Attribution.
Teams and projects first, people last
Cost conversations start with aggregates: which team, which runtime, which model. Today ClawMetry rolls usage up by runtime, model, session and agent, and by team through runtime-to-team mappings. A per-project view with budgets is not in a released version yet; a pilot can agree how projects are identified.
Opening an individual session is for investigating an expensive run or an incident, and access to it should be limited to the people allowed to see it. ClawMetry does not rank developers. Tokens, session length and generated lines do not measure the value of a person's work, and this page does not use them that way.
Limits that act on spend are covered in Budgets and limits: alerts work on their own, and a hard limit needs model traffic routed through the local proxy.
Compare alternatives by cost per accepted task
A cheaper model or agent is not cheaper if it fails more often. When you compare two alternatives, use one number for both:
Cost per accepted task = the cost of every attempt, including failed attempts and retries, divided by the number of tasks accepted, where both alternatives are held to the same acceptance criteria.
ClawMetry supplies the cost side and the signals that an attempt went nowhere: sessions with no file changes, sessions that looped, errored or were stopped. Deciding what counts as accepted stays with your team. A saving suggested by a recommendation is a hypothesis until a comparison like this one measures it. See Reducing spend and Estimating the productivity gains from observing AI agents.
Illustrative: what token spend does to a fixed-fee margin
Illustrative arithmetic, not customer data. Every number below is an assumption chosen to show the calculation. It does not prove a saving and it does not show that agents replace anyone.
| Assumption or result | Planned | If AI usage runs over |
|---|---|---|
| Fixed project fee (assumption) | $100,000 | $100,000 |
| Delivery team and other project costs (assumption) | $76,000 | $76,000 |
| AI agent usage (assumption) | $4,000 | $10,000 |
| Project margin | 20% | 14% |
For scale, with the same caveat: a four-person project whose agents use $300 to $800 of tokens a working day would use $6,000 to $16,000 over 20 working days. Whether that is a problem depends on what the fee assumed, which is why the planned figure belongs in the budget from the start.
Sample monthly cost report
Sample layout with illustrative figures. This is the shape of report a pilot sets out to produce from your own data. The team names and amounts are invented and add up; ClawMetry does not generate this report as one document today.
- Period: August 1 to August 31
- Timezone: UTC
- Currency: USD
- Basis: usage value at published rates (not contract or invoiced spend)
- Completeness: of recorded tokens priced
- Attribution: by team mapping; unmapped usage shown as unassigned
| Team | Tokens | Usage value, USD | Note |
|---|---|---|---|
| Platform (illustrative) | 41.0M | $1,240.00 | Mapped |
| Payments (illustrative) | 28.5M | $860.50 | Mapped |
| Unassigned | 10.1M | $312.25 | Residual: usage not mapped to a team |
| Unpriced | 2.4M | Not priced | Models with no published rate; excluded from the total |
| Total | 82.0M | $2,412.75 | Priced usage only |
Start with a bounded cost pilot
Contract valuation, billing reconciliation and project reports need your data and your rules, so they start as a pilot rather than a feature switch.
- One team, the runtimes you agree on, and written acceptance criteria before anything is measured.
- Objective 1: a cost baseline for that team at published rates, with unpriced and unassigned usage listed.
- Objective 2: an agreed way to attribute usage to projects, and a report in the layout above.
- Objective 3: where you supply a rate card or a billing export, a comparison against it with the residual shown, not hidden.
Scope and pricing are by agreement. No saving is guaranteed.
More on security, deployment and procurement is on the Enterprise page and the trust hub.